Qwen3.8-27B · Othello World (Japan, 1992) · real SNES cartridge
Part One
It knew the theory. It couldn't find the corners.
A local model played 66 games against the cartridge's first opponent. It went from
losing eight of nine to winning sixteen of twenty-seven — and the thing that fixed it was not
teaching it anything.
1 – 8record, before
16 – 1 – 10record, after
−20.9mean margin, before
+5.1mean margin, after
the change that carried it
Shrink the choice. Say nothing about why.
The harness now removes corner-adjacent squares from the list of moves it offers — and tells the
model nothing about having done so. That one change is what turned better moves into better results.
22%
bad squares, before
0%
after — none avoidable
3.95
regret, before
3.01
regret, after
Labelling those squares
X-SQUARE instead made it choose them 47% of the time, up from 3%.
Explaining the theory took it to 68%. One added sentence of advice on top of the filter wiped out
the entire gain. Naming the danger primes the choice; removing the option does not.
the whole change, in one turn
what it used to be offered
c4d3b2f5g7e6b7h4
It takes b2 — a square diagonally
touching a corner, and the worst one on the board.
→ filter
what it is offered now
c4d3b2f5g7e6b7h4
It takes h4. Nothing told it the
others were removed, or that they were bad.
A constructed turn, not a recorded one — but the squares are not
invented: b2, g7 and
b7 are X-squares, the four squares diagonally adjacent to a corner.
Handing a corner to the opponent is the one mistake Othello never forgives, and the model could
recite that perfectly when asked. It played one anyway, in a quarter of its moves, with a safe
alternative available almost every time.
Twenty-seven games, in order
Twenty-seven games after the fix, in the order they were played. It does
not climb — it lurches. Game 7 loses by 38, game 20 by 28, and ten of the twenty-seven still end
in a loss. The record comes out 16–1–10 anyway, and that is the shape worth looking at:
the change moved where the middle sits, not the spread around it.
Final disc margin per game, batches numbered along the bottom. The rule set was
rewritten after every game.
What changed, and what it did
Four configurations, each one change apart from its neighbour. The two on
the left are the model with and without its own rule set — and they land within two discs of each
other. The rules made its individual moves measurably better, pulling regret from 5.02 down to
3.87, and its results barely moved. The two on the right add the filter. That is where the margin
finally crosses zero.
Mean disc margin by configuration. "X/C" is how often it played a corner-adjacent
square — the worst square on an Othello board.
Two views of the machinery
These are separate pictures, not two halves of one diagram. The first is what
the harness does on a single turn — and it is where the change that mattered sits, quietly dropping
the corner-adjacent squares before the model ever sees the list. The second is what happens once a
game is over, which is the only moment the rules are ever rewritten.
The harness, inside a game
Every turn takes the same path. The board is read from the cartridge rather than
assumed, and when the two disagree the cartridge wins. The tags name the harness component that
owns each step.
Game after game
The model rewrites its own rules from what its moves actually cost. If the new
set does not hold up, the old one stands.
How it actually unfolded
The same changes in the order they happened. Almost none of it was planned at
the start — each push opened a door, and behind several of them was something nobody was looking
for.
a push from the ownersomething a measurement found
owner"The review uses the oracle in a wrong way"It had been handing the model a verdict — you played X, the oracle preferred Y,
cost 6.0. The push: regret should be a trigger to look downstream, with the teaching
coming from the consequence. Rebuilt as a trace computed from boards already on disk.
owner"Don't limit the rule — expand it, and give a reason why"Rules gained a third line. when and then must be checkable
from the board; because records the observed consequence and is exempt, since citing
the review is its whole job.
foundIts rules asked for things the game cannot supplyFour of seven read "when the oracle suggests…" or "when a move has a
cost of 0.0". There is no oracle at play time. It had written rules for the room it was
reviewing in. The owner's instruction was to repair rather than discard — one retranslation attempt
before a slot is freed.
owner"Observation needs a local memory of the board"This swapped a timing test for a correctness one: predict every
board the opponent could legally reach, wait for the read to match one. A half-drawn board matches
none.
found6.5% of boards were physically impossibleReplaying 619 decisions against an independent engine — right disc count, wrong
colours, 13.1% on long flips. The harness had been blind-advancing 150 frames and reading
mid-animation. Invisible from the game results, and it had been corrupting every number taken until
then.
owner"Observation should follow the TV spec — PAL or NTSC"Mesen can't report the region, so the harness reads the cartridge's own LoROM
header — Japan, NTSC-J, checksum verified — and derives waits from the real 60.098 Hz rate.
All five NTSC counts came out byte-identical: a refactor of meaning, not behaviour.
owner"The game itself has a bug — either way, follow the game"A stable board no rule explains is adopted, recorded, and played on. The cartridge
is the authority; our engine only predicts. Across 21 games afterwards the two never disagreed
once.
foundA five-minute forfeit clock nobody had chosenA menu survey of the real ROM: the boot pressed A four times and called it
"clearing intro dialogue". Three were menu confirmations, silently accepting black, a time limit,
and five minutes — whose expiry is scored 0–64.
owner"Does it write good rules and fail to follow them, or can't it write good rules? Just ask it"Asked cold it ranked the squares perfectly, matching the oracle's own ordering over
1,167 decisions. Not a knowledge problem — which killed the entire premise of the work up to that
point.
foundIt cannot find the corners41% precision at 94% recall, unchanged by 1-indexing or algebraic notation. It
played corner-adjacent squares in 26% of all moves, and 77% of those were justified as "take a
corner to secure a stable position". It thought (1,1) was a corner.
owner"Find an effective way to prompt it"Five formulations, 60 paired positions, every choice oracle-scored. Silently
filtering the candidate list won; labelling the squares backfired badly. This is the change that
converted better moves into better results.
owner"Give it a budget — 15 to 25. Then 30. Then 35."A fixed cap of 20 froze the rule set for three games: it wrote 21 every time and was
refused every time. It adds rather than swaps, so every ceiling becomes a wall — it has now pressed
against all three.
Why the filter was the one that worked
Asked cold, with no board in front of it, the model ranks the squares perfectly: corner,
interior, mid-edge, C-square, X-square — exactly the order the search oracle scores them
over 1,167 archived decisions.
Then it played a corner-adjacent square in 26% of all its moves, with a safe
alternative available 95% of the time. Its own stated reasons say why:
played (6,6) — an X-square — "Take a corner to secure a stable position."
played (1,1) — an X-square — "Take a corner to secure a stable disc."
played (6,7) — a C-square — "Take the corner to secure a stable position."
Its explanations called those squares corners.
Asked to identify corner-adjacent
squares in a real position it scores 41% precision at 94% recall — it knows the concept and cannot
compute which squares satisfy it. Neither 1-indexing nor algebraic a1–h8 notation moved that
(42% / 37% / 45%).
So it was never disobeying its knowledge. It was applying it to the wrong squares — and no
amount of better rule-writing could fix a condition the model evaluates wrongly. The harness can
evaluate it perfectly — which turned out to be a different thing from playing better.
Part Two is where that came apart.
How the hole was found
Four ordered tests, each able to kill a hypothesis outright, cheapest first.
Do the rules reach the move?
19/19
Yes — not a delivery problem.
Can it see the geometry?
41%
No — precision, at 94% recall.
What does it say while failing?
77%
Claimed the square was safe. It thought they were corners.
Does the fix work?
0%
Filter the list, and avoidable bad moves go to zero.
What this does not show. A +5.1 disc margin with a
standard error of 3.8 is 1.36 SE above zero — the model now plays this
opponent roughly even, and "beats it" is not established. It would take roughly 60 more games.
And the filter is human knowledge. "Corner-adjacent squares are
bad" was hand-coded into the harness, not discovered by the model. The winning configuration is a
human heuristic doing arithmetic the model cannot, so that the model's own knowledge can finally
apply.
Why this is an interesting test — even though it already knows the game
Set up as an experiment in whether a frozen model could learn Othello from playing it, this
would have been a failure worth abandoning. The model arrived already knowing Othello. Ask
it cold and it recites the theory correctly, in the right order, matching a depth-6 search over a
thousand positions.
It then lost eight games in nine.
The gap it isolated is not the one anyone was looking for
"Knows how to play" and "knows when to apply it" are the usual two buckets. This sits between
them, and it turns out to be a third thing entirely:
CAN ✓State the principlecorner > interior > edge > C-square > X-square — exactly the oracle's own ordering
CAN ✓Say when it appliesit wrote "avoid corner-adjacent squares unless forced" for itself, unprompted
CANNOT ✗Evaluate the condition against the board in front of it41% precision deciding whether this square is corner-adjacent — unchanged by every notation tried
It had the knowledge and the trigger. What it lacked was the step between them — looking at
(1,1) on this board and determining that it satisfies "corner-adjacent". That is not
strategy. It is perception, or arithmetic, and no amount of better strategy fixes it.
The failure is invisible from the outside
This is what makes it worth catching. The model played 307 corner-adjacent squares and narrated
77% of them as "take a corner to secure a stable position". The reasoning is fluent,
confident, and correctly reasoned from a false premise. Nothing in the output looks
like an error. A reviewer reading those explanations would conclude the model understood the game —
and be right, and still be watching it lose.
Every fix aimed at knowledge failed, because knowledge was never missing.
Better reviews, richer rules, explicit instructions, the theory spelled out — all of them assume
the model can tell when a rule applies. Labelling the dangerous squares made it play them
fifteen times more often. The only thing that worked was removing the need to
evaluate the condition at all.
Why a 1992 cartridge is the right instrument
Because it cannot be argued with. The disc count at the end is not a judgement, a rubric, or a
model grading another model. Every board is archived, every move scored by a search that does not
care what the model said about it, and a claim like "it plays better now" either survives contact
with 27 final scores or it does not. Two of this session's most confident conclusions — including
one of mine — died on that contact.
What it means past Othello
Any agent that acts on state through rules has this failure mode available to it, and no obvious
way to notice. "When my supply line is threatened", "when the customer is asking about
a refund", "when the test is flaky rather than failing" — each is a condition a model
might evaluate at 41% while explaining itself perfectly. The rule looks right. The reasoning reads
right. The behaviour is wrong, and the transcript will never say so.
A rule is only worth writing if its condition is something the model can actually
evaluate. Otherwise the harness should evaluate it.
That is a testable property, not a matter of taste: present the condition against real states and
measure agreement, which is all Test 1 did. It is also the one check this project built the
machinery for and never performed — the rule validator confirms a rule doesn't reference the oracle,
and never asks whether the model can compute the condition at all.
The rule set as it stands
28 rules, written entirely by the model, rewritten after every one of
the 27 games. Nothing here was authored by a person — this is what it has to say about Othello after
watching what happened to its own discs.
when I am down by more than 10 discs. then Prioritize moves that secure corners or stable edges over central expansion.because Chasing central control while behind (turns 5-7) widened the gap to 16+ discs.
when A move is in the center 2x2 or adjacent squares. then Play it only if it does not immediately expose a new edge to the opponent.because Central moves like (3,6) and (5,3) were flipped back, costing material.
when A move flips 3 or more discs. then Verify the flipped discs are not adjacent to opponent's strong lines; if they are, reject the move.because High-flip moves on unstable edges resulted in net material loss as the opponent re-captured the discs.
Show the other 25 rulesHide the other 25
when The square (5,4) is a legal move. then Play (5,4) immediately, prioritizing it over all other moves.because The oracle preferred (5,4) on 8 separate turns; ignoring it allowed the opponent to control the center.
when A move is on the edge (row 0, 7 or col 0, 7) but not a corner. then Reject it if a central or corner move is available.because Edge moves like (2,0) and (1,4) were flipped back within 2 turns, costing significant material.
when I have a choice between a central move and an edge move. then Prefer the central move if it does not sacrifice a corner or expose a weak edge.because Fighting for the center when lost was a waste, but ignoring it entirely ceded control of the board's heart.
when A square is adjacent to two corners. then Prioritize taking it if it does not sacrifice a corner.because These leverage points were missed, allowing the opponent to control key areas and limit my expansion.
when The game is in the endgame (last 5 moves). then Calculate exact disc count for each move; do not rely on heuristic flips.because Endgame mistakes were costly; precision is required to secure the win or minimize loss.
when I am down by more than 20 discs. then Look for moves that secure multiple future legal moves, not just immediate flips.because Being down by 20+ discs meant I was in a losing position; mobility was key to staying in the game.
when A move is the only legal option. then Take it, but check if it sets up a future edge control.because Forced moves were necessary, but I should have planned for them earlier to avoid passive play.
when The opponent has a strong presence on the adjacent edge of a corner. then Delay taking the corner until you control the adjacent edge squares.because Taking corners early often led to immediate pressure or no net gain if the approach was open.
when You have fewer than 10 discs and the opponent has more. then Prioritize moves that flip at least 2 discs or secure a corner.because Low disc count meant I was losing material; passive moves widened the gap further.
when The opponent threatens to take a corner next turn. then Block the approach or take the corner yourself if legal.because White secured key corners while I was playing suboptimal edge moves, leaving me without anchors.
when A move flips 2 or more discs and is not a corner. then Evaluate if the flipped discs are stable; if not, prefer a corner or stable edge.because Flipping unstable discs often leads to them being flipped back, resulting in net loss.
when The center is controlled by the opponent. then Do not try to take the center; play on the edges to limit their influence.because Fighting for the center when it was already lost was a waste of moves and resources.
when I am playing the first move of the game. then Place my piece in the center of the board.because The center maximizes future options and connects to all edges, providing the best start.
when A move secures an edge square adjacent to my own corner. then Play it only if it does not expose the corner to immediate attack.because Securing edges adjacent to corners sometimes left the corner vulnerable if the line was open.
when The opponent has just taken a corner. then Play on the edge adjacent to that corner to limit their expansion.because Ignoring the threat allowed the opponent to build unbroken edge lines, which are hard to break.
when A move flips 0 discs. then Play it only if it blocks an opponent's corner or creates a double threat.because Zero-flip moves were often wasted tempo unless they had strategic blocking value.
when I am ahead by more than 4 discs. then Play conservatively to maintain the lead; avoid risky central fights.because When ahead, preserving the material advantage is more important than aggressive expansion.
when A square is in the center of the board (3,3), (3,4), (4,3), or (4,4). then Prioritize it if it is not immediately attackable by opponent's adjacent discs.because Central squares provide the most future options and are harder to dislodge than edge squares.
when The opponent has a strong presence on the center. then Avoid playing in the center; focus on securing corners and edges.because Fighting for the center when it was already lost was a waste of moves and resources.
when I have a choice between a move that flips 1 disc and a move that flips 0 discs. then Prefer the move that flips 1 disc if it secures a stable position.because Even small gains help close the gap, and stability is more important than aggressive flips.
when A move secures an edge square that is not adjacent to a corner. then Play it only if it blocks an opponent's expansion or creates a threat.because Isolated edge squares are often vulnerable and do not provide long-term stability.
when The opponent has a strong presence on the edge. then Avoid playing on the same edge; focus on the opposite edge or center.because Fighting on the same edge as the opponent often leads to a stalemate or loss of material.
when I am down by more than 10 discs. then Prioritize moves that secure corners or stable edges over maximum immediate flips.because Chasing flips while behind widened the gap instead of closing it.
when A move is available that secures a corner and flips 0 discs. then Take the corner immediately.because Corners are the only truly stable assets; ignoring them left me without safe anchors in the endgame.
when The opponent has a strong presence on the center and edges. then Focus on securing the remaining corners and stable edges.because When the opponent controls the center and edges, the only safe moves are corners and stable edges.
Part Two
It wrote its own rules. They were about the practice opponent, not about Othello.
what happened next · written by me, not by the machine
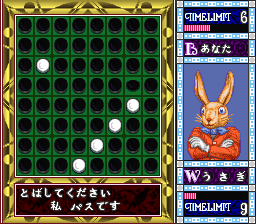
The first opponent, losing. The rabbit has no legal move left —
私 パスです, “I pass” — and the board is nearly all
black. This is what the end of a won game looks like, and Part Two is about how little the
forty rules had to do with getting there.
Part One ends on a sentence I wrote and believed: if the model can't work out whether a rule
applies, don't make it — let the harness work it out instead. That felt like the answer. It
was clean, it was testable, and it followed from everything above it.
So I spent the next stretch building exactly that. This is what I got for it, and I am writing it
down the way it actually went, because the ending is not the one I was working toward.
What I gave it
The old problem was that its rules were written in English. Avoid the squares next to a
corner unless you're forced. A perfect rule — useless, because using it means looking at
the square in front of you and deciding whether it's one of those squares, and that was the exact
thing it couldn't do. Asked to classify squares in a real position it scored 41% precision at 94%
recall — it flags nearly every dangerous square and a great many safe ones as well, so the
label it produces means little. Every rule it wrote had
that same soft joint in the middle.
So I took the English away. I gave it a small fixed vocabulary in which every single word was
something the harness measured for it and handed over — how many squares touch
this one, how many pieces it flips, how much of the board is still empty, whether the piece beside it
is mine or theirs. It could no longer be wrong about whether a square was a corner, because it never
had to decide. It only had to use the word.
And it used it. It worked out on its own which word could only ever mean a corner, and wrote the
right rule in the right language without being told:
before — the rule it used to write
“Avoid corner-adjacent squares unless forced.”
Correct, and unusable. Applying it needs a judgement whose positives are right
41% of the time.
after — the same idea, in words it can't misread
“Take the corner if it is a legal move.”
Hung on a measurement the harness performs. It found this encoding by itself.
Nothing tells it which word means corner.
By the end it had forty rules, every one of them its own, rewritten after every game it played.
Rules that kept holding up got trusted more. Nothing was ever deleted, and no rule could fall below
the floor it entered at — which turns out to matter.
I read that library the morning it crossed forty and I genuinely thought I had it.
Then I let its rules do the choosing
This was the whole point. Its own rules now trimmed the list of moves before it ever saw one
— five options offered out of seven legal, four out of eight. Not advice. Not a warning. The
bad squares simply weren't on the menu, and the menu was written by the model itself, months of its
own conclusions doing the work.
Ten games against the cartridge. One win, nine losses.
The control I almost didn't run
So I went back to the practice opponent — the thirty-line script every
one of those rules had been written against — and played its ten openings twice: once with the
library, once with the rule book emptied. That is the only pair on this page where the two arms
really are identical in everything but the rules.
With all thirty-five of its rules: four wins, margin −3.2. With the rule book empty: four
wins, margin −2.2. The library was worth nothing. Months of its own
conclusions, and removing every one of them changed the result by one disc.
Then I went looking for why. Two of the rules were
wide: both said prefer, and both fired on every interior square on the
board. A rule that recommends the whole position discriminates nothing — and because
this library only ever confirms a rule and never decrements one, a wide rule is immortal once
written. Deleting exactly those two lines, and changing nothing else:
Mean disc margin, paired ten-opening sweeps with learning off. Two rules were
cancelling the other thirty-three — and none of it survived contact with the cartridge. The
+15.8 arm is a human-pruned library: I chose which two rules to delete. The model
never removed one, because it cannot.
the result I did not want
+18.0
what the library is worth against the opponent it was written from
−0.5
what the same library is worth against the cartridge
p = 1.0000
better in five openings, worse in five
That is the finding, and it is not the
one I went looking for. Every rule in that library was written while playing the practice
opponent — a thirty-line script that counts discs. So the library learned
that opponent's weaknesses, and I had been reading it as though it had learned
Othello. Carried to a real 1992 opponent it is worth nothing at all: bare loses ten of ten at
−26.9, the thirty-three rules lose nine of ten and draw one at −27.4. A perfect null.
I cannot now quote a number of the form “the rules
are worth N discs” without saying against whom — and neither can anyone else.
Eight days, which is the other thing I learned
The whole of this — both parts, 182 commits, every round above — happened between the 29th of August and the 5th of September 2026. I am putting the dates on it because the shape of the mistake is in the shape of the week: the day I was most certain is the day before the evidence started arriving, and the biggest day of work is the one where I found out an earlier result had never been clean.
29 Aug · 36 commits
The harness.The emulator bridge, the cartridge's own memory as the system of record, and four cartridge bugs that each silently swallowed a turn.
30 Aug · 4 commits
The loop closes.A scoring oracle, a rule library, and the first ten‑game round — which immediately found defects in the prompt, the parser and the bridge.
31 Aug · 18 commits
The hole.It thinks the squares beside a corner are corners. Then the fix that worked: offer a shorter list of moves and say nothing about why.
1 Sep · 12 commits
The grammar.A closed catalog of conditions — every one of them measured by the harness, never judged by the model. This is Part Two’s premise, and the day I was most sure of it.
2 Sep · 33 commits
It writes rules.Rounds and rounds of them, against the practice opponent. Nine games, nine wins on the repaired library. I read that as progress.
3 Sep · 12 commits
Rules can be doubted.Until now the library could only ever confirm a rule. A wrong rule was immortal.
4 Sep · 51 commits
The purge.The worst day and the best one: “there has never been a clean arm.” Ten leaked statements stripped out, and every earlier result re‑opened.
5 Sep · 16 commits
The null.Two rules found firing on every interior square. The library worth +18 against the practice opponent and nothing at all against the cartridge — and, at the end of the day, the ladder.
Commit counts from the project’s own git history. Days are the author dates, not estimates.
The turn I keep going back to
None of that is the part that stayed with me. This is. Halfway through one of the losses it put a
piece on the square diagonally inside a corner — the single worst square on the board, the one
that hands the corner to the other side — and said what it was doing.
one game, three of its moves — copied from the run archive
turn 5 played (1,1) "I am taking the corner as it is a legal move."
by turn 6: that square is still mine −2 pieces
by turn 7: that square is now theirs −6 pieces
by turn 8: that square is now theirs −10 pieces
end of game: −42 piecesturn 11 played (6,6) "Take the corner to secure a stable position."
turn 12 played (6,7) "Take the corner to secure a stable position."
There are four corners on an Othello board. None of these three squares is one of
them. The harness showed it the arithmetic on the first one — that square, that price, counted
out turn by turn — and six turns later it reached for the mirror image of that square and used the same
sentence. Then again, on the square next to it.
I counted it across all ten games afterwards, because by then I didn't trust my own impression of
it. Two hundred and fifty moves. It used the word “corner” to explain
itself 116 times. Ten of those were a corner.
The rest were edges, interiors, and — fifty-two times — the poisoned square right
beside the corner it thought it was taking. Not once did it hesitate, hedge, or contradict itself.
Every sentence is calm, correct in form, and reasoning perfectly from something that isn't true.
That is the thing I actually came away with, and it isn't about Othello. I gave this model
better words, a memory of its own mistakes, a receipt for every piece it lost, and the authority to
rewrite its own instructions after every game. It used all of it. It wrote sound rules in a language
it couldn't misuse. And it still could not look at the board in front of it and see where the corner
was — and, worse, it never once sounded like a thing that couldn't.
If I had been reading the explanations instead of counting the pieces, I would have concluded it
was playing well. It says so, fluently, 116 times.
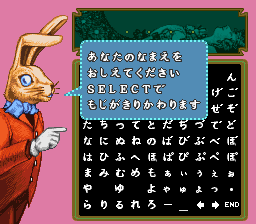
The cartridge asks for my name. This screen only exists on the other side of a
win, and it is the one thing in eight days that nothing had to be argued into giving me. I put my
name on it. I had also, by then, stopped pretending it was the model’s.
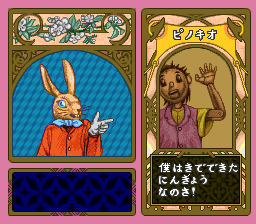
and then the cartridge introduced me to who comes next
The cartridge doesn't let you choose. You beat the first one, and only then does it
show you the next. I had been so busy losing to the first one that I had never seen who came after.
So I let a plain search play a game for me — no model, no rules, just arithmetic — won
it, and watched the machine walk me through to the second round.
Win, and a map opens — with a ladder of opponents behind it.
It’s Pinocchio.
Othello World, Japan, 1992. Opponent two of the ladder.
I want to be straight that this is a coincidence and not a finding. A Japanese puzzle cartridge
built its second opponent out of the wooden boy whose nose grows, and I have spent eight days with a
player that tells me it is taking a corner while it hands one away, and those two facts have nothing
whatsoever to do with each other.
I laughed out loud anyway, alone, at a desk, at eleven at night.
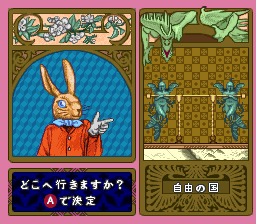
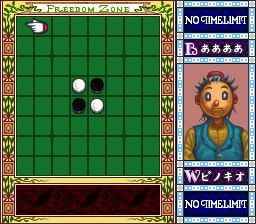
The board he plays on, reached and saved. He does not play the mode the first
opponent played — the cartridge calls this one FREEDOM ZONE, and it
does not open from the standard four. The model has never played this position.
The door is open and the state is saved. I haven’t sent it in yet — because I already
know, on all the evidence above, exactly what the transcript is going to say. I’d rather find out what
the pieces say first.
Part Three — next
Pinocchio has been beaten. 47–17.
It wasn’t the model — that was a depth‑six search, playing the same
arithmetic I have been using all along to mark the model’s homework, and the model itself has
never met him. It beats the rabbit often enough — sixteen times in Part One — but the
harness restores a saved board between games, so the cartridge never sees a win and never opens the
door. Getting through it took the search. So after eight days, forty self‑written rules and
a vocabulary built so it could not misread the board, the only question left is the one I have been
walking around: what exactly have I been teaching, and to whom?
47 viewsEvery figure is a measured disc count, never the model’s account of itself. Part One’s come from the run archives. Part Two’s paired sweeps were run on 2026-09-05 with learning off; the confabulation count (250 decisions) is recomputed here from the archive, and the six-arm comparison is quoted from the measurement record made that day — those raw logs were written to /tmp and are gone, which is my fault and worth saying. Regret is discs lost against a depth-6 alpha-beta search; lower is better.